Give each question room, but keep the comparison intact
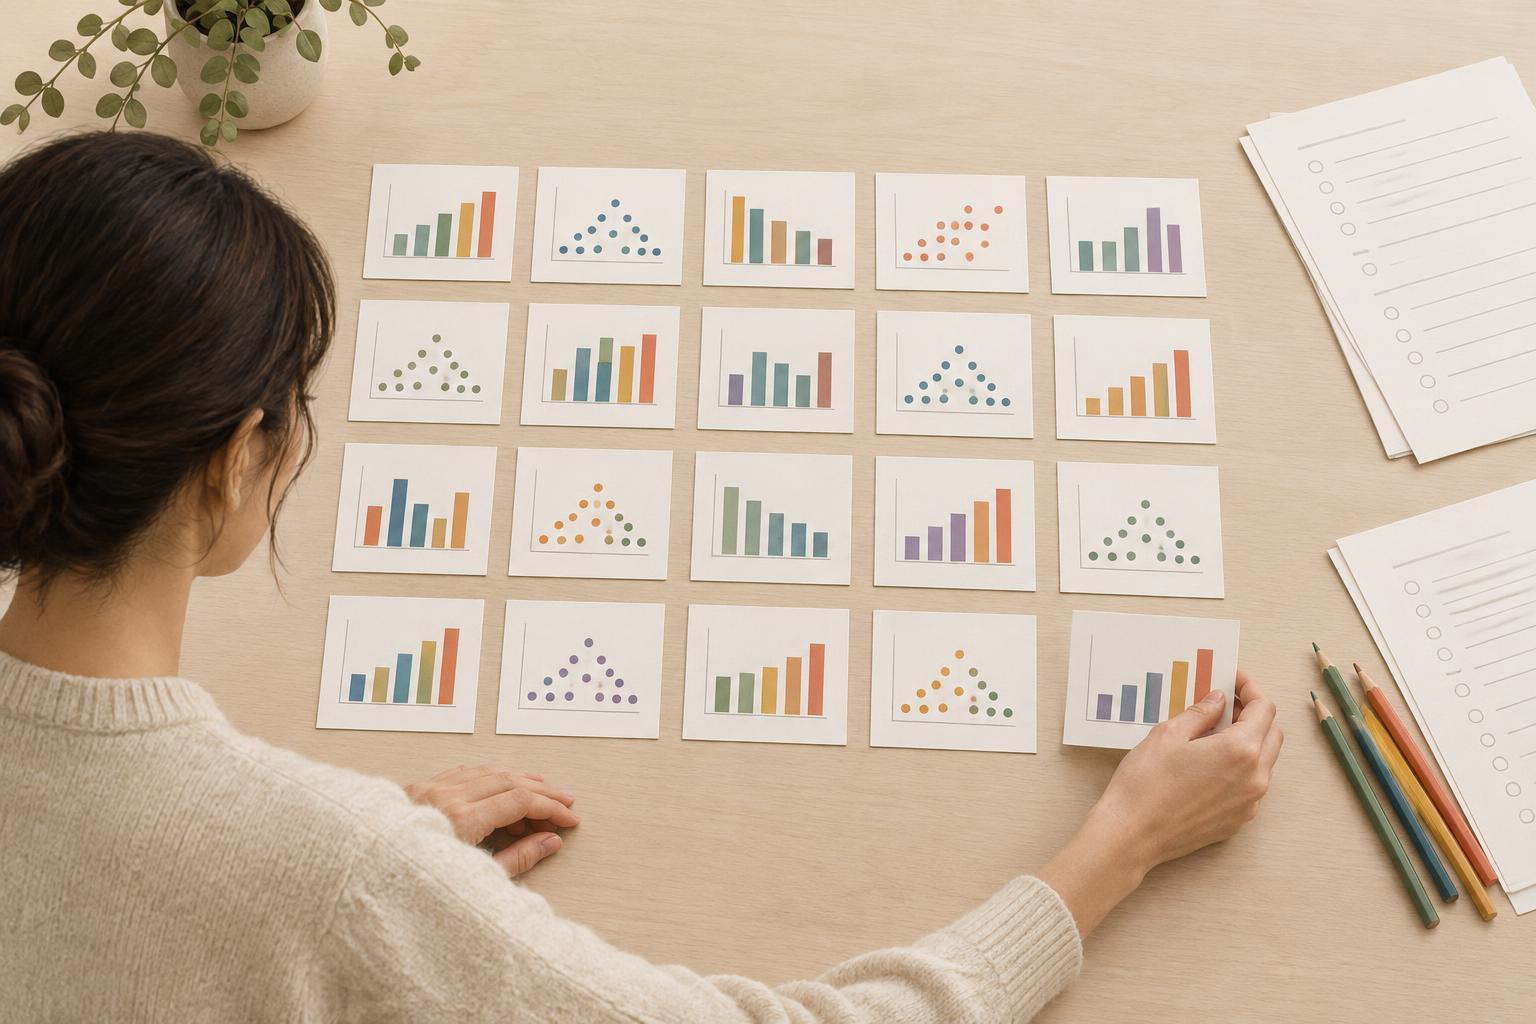
Suppose a survey asks customers to rate the ease of finding information, placing an order, and getting help. Putting every response category for every question into one chart can create a tangle of bars and labels. Small multiples offer another approach: make one compact chart, or panel, for each question and arrange the panels in a grid. Readers can inspect an individual question while scanning across panels for a broader pattern.
This works best when the questions are genuinely comparable. Items using the same response scale, such as a five-point agreement scale, are natural candidates. A question about purchase frequency and one about satisfaction may both be interesting, but placing them in identical-looking panels could imply a comparison that does not make sense. Before drawing the grid, write down the specific task it should support: comparing response distributions, finding unusually low ratings, or checking whether audience groups answer differently.
Choose one visual rule for every panel
A simple set of horizontal bars can show the percentage selecting each response option for a question. For ordered rating scales, stacked bars can make the overall distribution compact, although middle segments are harder to compare precisely because they do not share a common starting point. If the main question is how many respondents gave a favorable answer, a single bar per panel may be clearer. Define “favorable” next to the chart rather than leaving readers to guess which options were combined.
Keep the scale, response order, color meanings, and label placement consistent. If a 40% bar fills one panel but only half of another because their axes differ, visual comparison becomes misleading. Use the same percentage range across panels when percentages are the measure. Reserve a distinct color for a category you want readers to notice, and use that color for the same category everywhere. A neutral palette for other categories can reduce clutter without hiding their values.
Make the denominator and missing answers visible
Survey questions do not always have the same number of answers. Some respondents may skip an item; others may not see it because of a screening or follow-up rule. A panel labeled “68% favorable” tells an incomplete story if it does not say whether that percentage is based on all survey participants or only those who answered the question. Put the response count in each panel when counts vary, and state what the percentages exclude.
Handle options such as “not applicable” deliberately. Depending on the purpose of the chart, you might display that option as its own category or exclude it from a rating calculation. Either choice can be reasonable, but applying different rules to different panels without explanation makes the grid difficult to trust. If a question went only to a subset of respondents, identify that subset. Small multiples create visual consistency; the notes must make clear where the underlying questions differ.
Order panels to help readers find a pattern
Panel order is part of the explanation. Following the questionnaire order can help a team locate familiar items, while grouping questions by theme can help readers compare related experiences. Sorting by a stated measure, such as the share of favorable responses, makes high and low items easier to find. If you sort, identify the measure and keep the labels prominent so that the ranking does not become more memorable than the questions themselves.
Include a short takeaway that describes what the display shows rather than declaring a cause. For example, “Ease of ordering has a higher favorable share than ease of getting help” is a comparison a reader can check in the panels. “Customers dislike support because wait times are too long” goes beyond those ratings unless the survey also asked about wait times. When differences are small, counts are low, or groups answered different versions of a question, avoid presenting a rank as a firm conclusion.
Test the grid before sharing it
Build the first version with a handful of questions, then view it at the size your audience will actually use. Can someone read the full question wording? Are response labels legible without relying on a distant legend? Does the layout still work on a narrow screen or a printed page? If not, split the questions into themed grids rather than shrinking every panel until it becomes unreadable.
Finally, ask a colleague to answer two questions using only the chart: which items differ most, and what does each percentage represent? If they cannot answer quickly, revise the titles, scales, or notes. A good small-multiple display does more than fit many survey results into one space. It lets readers make the intended comparison, understand its limits, and decide which findings deserve a closer look.